№ 004 · data pipeline · history
[LIVE PRODUCT]Estadísticas: a century of club history as data
A century of club stats, searchable and sourced
Head of Engineering (volunteer) · Club Atlético Lanús · 2024 - Present
The club's stats site and API: 4,000+ matches and 1,500+ players from a century of history, sourced from ~238,000 scanned pages through a data pipeline with provenance.
- TypeScript
- Express
- Sequelize
- Postgres (Neon)
- Next.js 16
- Vercel (Cron, Blob, AI Gateway)
- Satori
- Vitest
The problem
Club Atlético Lanús was founded in 1915. Its history lived in printed yearbooks, magazines, a CD encyclopedia and the memory of a few volunteers. The museum wanted every match, player and coach searchable, and correct.
I made the first commit of every repo in this project and wrote the large majority of the code since 2024.
A data pipeline with provenance
- ~30 enrichment modules pull from Wikidata, Transfermarkt, BDFA, ESPN, RSSSF, Wikipedia brackets and even ERA5 weather reanalysis for historical match days.
- Every loader runs dry-run → snapshot → apply, and stores where each fact came from, so conflicting sources can be compared instead of overwritten.
- A gap audit publishes what is still missing.
- The archive review log covers about 4,300 scanned files / 238,000 pages (yearbooks from 1907 to 2022, continental magazines), with OCR caching and deduplication.
The result: 4,000+ matches and 1,500+ players with lineups, formations, cards, penalties, coaches, referees, stadiums and shirts, in a 59-model Postgres schema.
Products on top
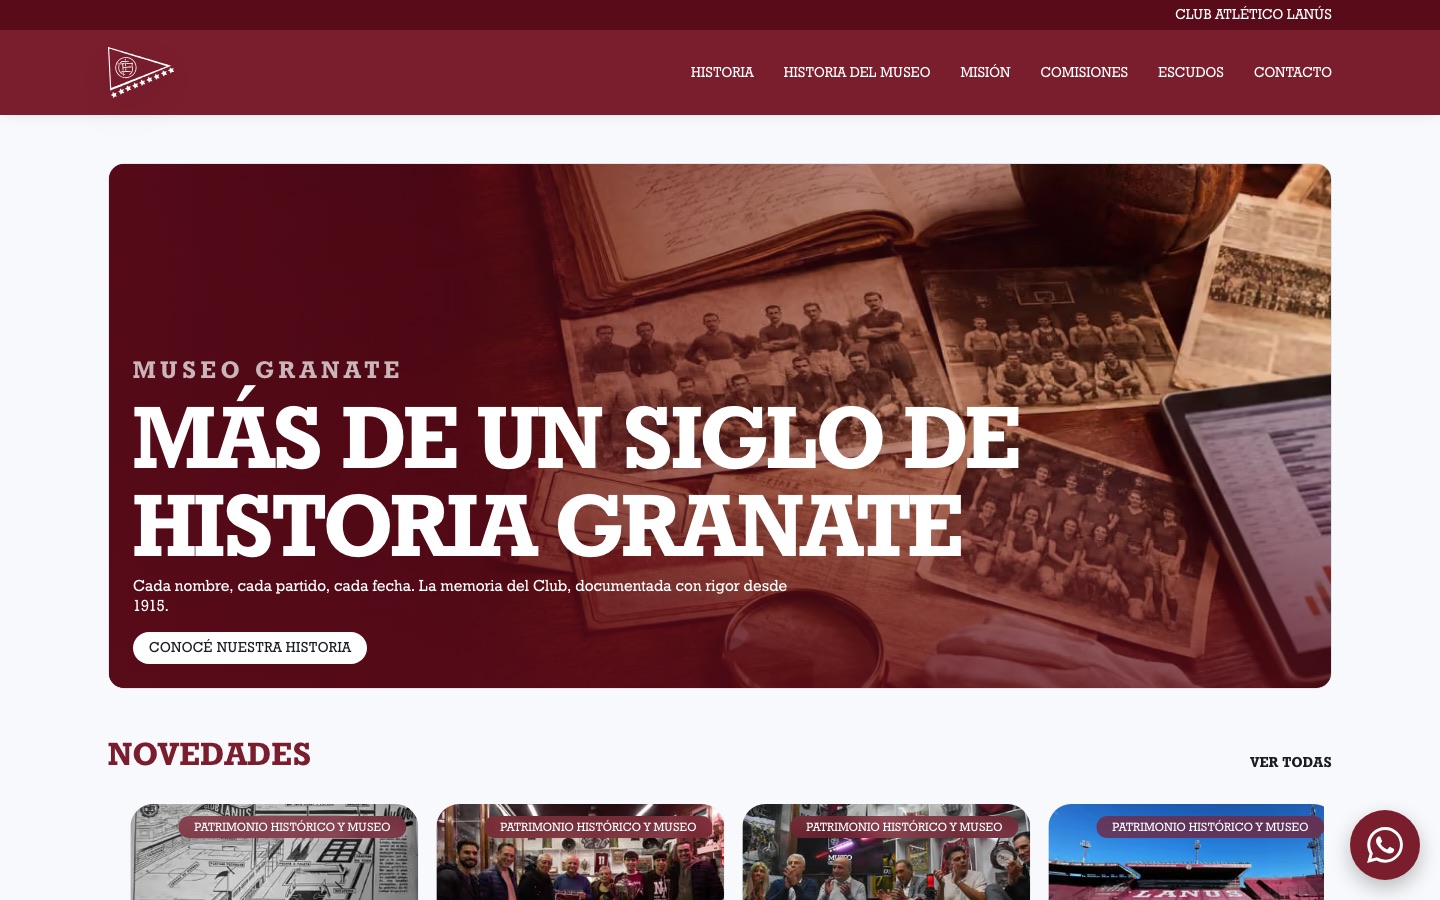
- Museo Granate, the museum site (10,000+ monthly users).
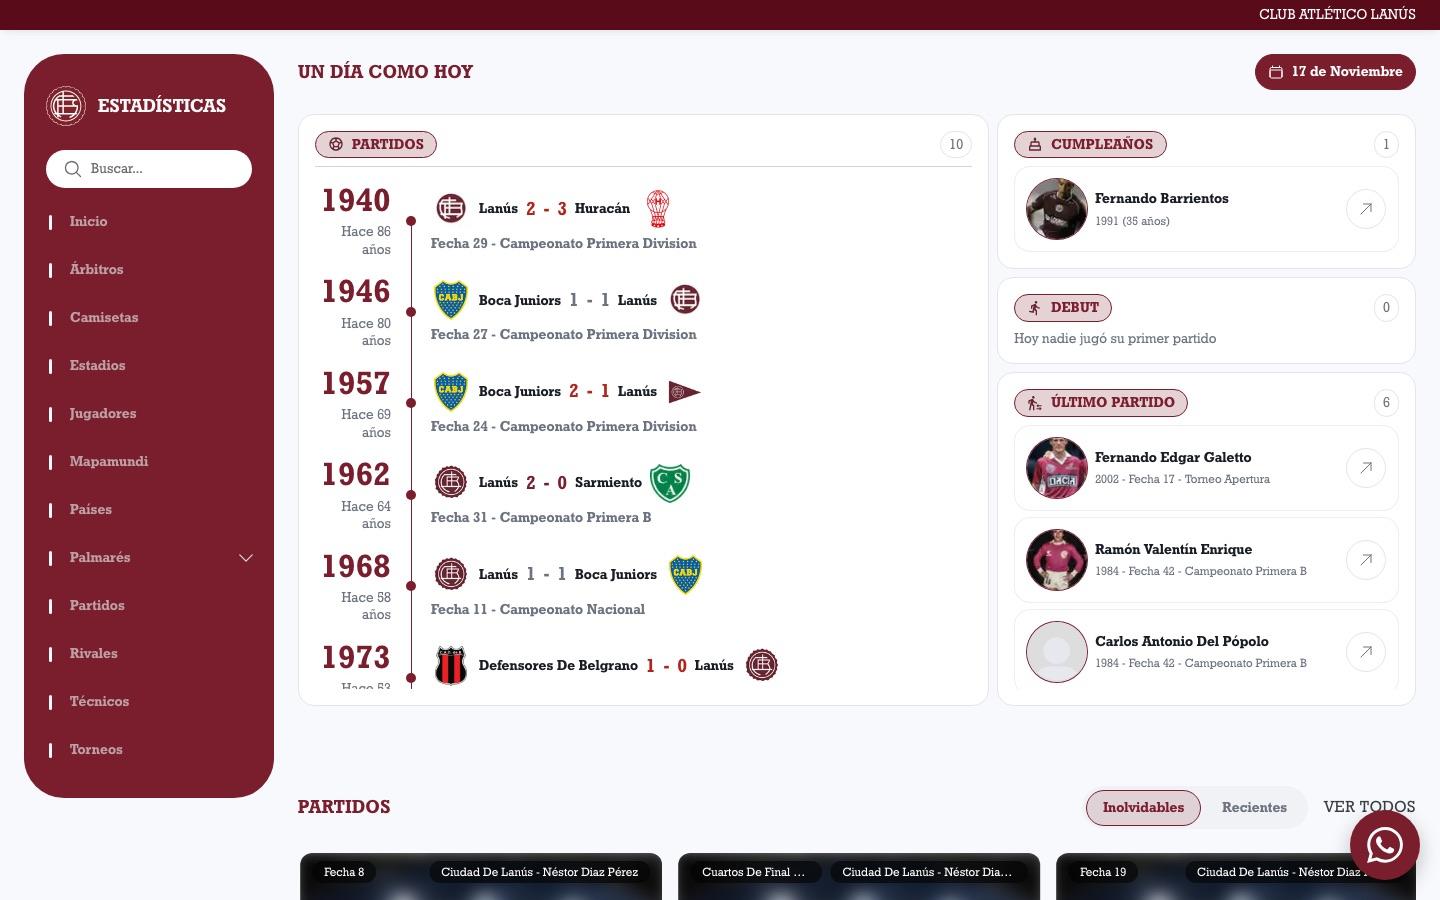
- Estadísticas, which I split out into its own product: about 25 sections rebuilt to the new design in six weeks, match pages with formations on the pitch and weather, player and coach careers, head-to-head, and a stadium map. It calls the API only through a server-side proxy with an endpoint allow-list.
- Search with Postgres
unaccent+pg_trgm(fuzzy, exact and prefix strategies). - "On this day": a daily cron finds birthdays, debuts and anniversaries, renders branded cards with Satori, writes captions with an LLM through the AI Gateway (no stored API key) and emails them to the museum team.
Engineering
- JavaScript → TypeScript and CommonJS → ESM migrations on a live API.
- Integration tests on a schema-only database branch; all 61 write endpoints covered, enforced by a test that walks the router.
- On-demand revalidation of four websites after every CMS write, purging the CDN before the webhook so no site re-fetches a stale copy.